Case Study: LTE Network Troubleshooting & Provider Blocking Crisis
Managed Connectivity • Network Diagnostics
Strategic Summary: When an upstream provider began randomly blocking LTE routers, multiple client network infrastructures faced sudden, systematic failures[cite: 1]. By implementing a rigorous diagnostic methodology and coordinating directly with provider engineering teams, Si Futures bypassed the blocking mechanisms and deployed a diversified, multi-provider network architecture that restored a 99.8% uptime baseline[cite: 1].
Challenge: Unpredictable Network Failures
Network connectivity failures during peak business operations create cascading problems across multiple organisational systems[cite: 1]. When an upstream provider began randomly blocking LTE routers, client infrastructures faced systematic drops that directly threatened business continuity[cite: 1].
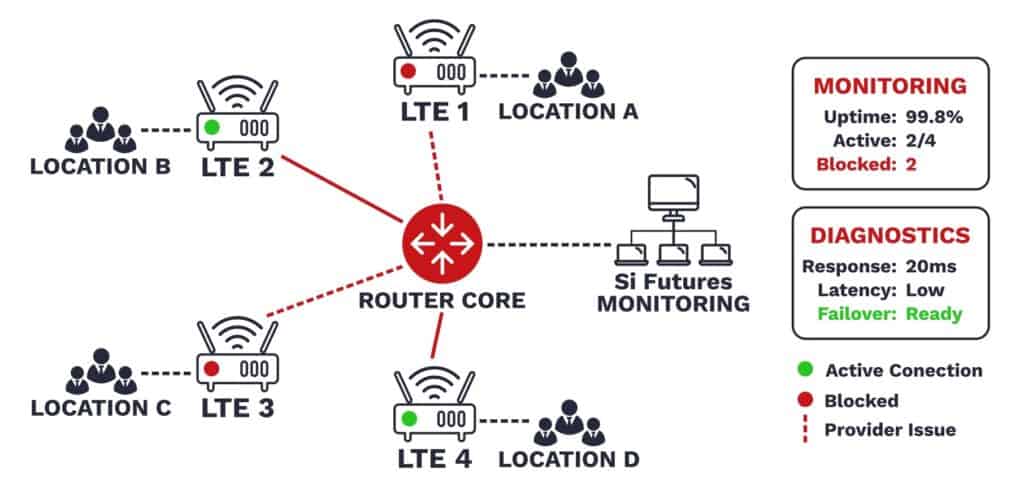
Figure 1: LTE network topology overlay showing affected router endpoints during random carrier blocking events[cite: 1].
The technical challenge extended far beyond simple connectivity restoration[cite: 1]. Random blocking patterns made troubleshooting particularly complex[cite: 1]. Because there was no consistent pattern in affected router models or configurations, and blocks occurred without advance technical justification, traditional diagnostic tools could not isolate the initial triggers[cite: 1].
A Systematic Investigation Approach
Rather than implementing temporary, reactive fixes, we developed a deep root-cause investigation procedure[cite: 1]:
- Network Traffic Analysis: Comprehensive examination of router communication packets to isolate specific blocking triggers[cite: 1].
- Provider Technical Coordination: Direct, backend engineering-level engagement with the provider’s team to identify unannounced policy changes[cite: 1].
- Impact Assessment: Systematic evaluation of affected client sites to prioritise high-severity dependencies[cite: 1].
The Solution: Immediate Protocols and Long-Term Architecture
Resolution required more than simple router replacement[cite: 1]. Our immediate protocol involved an emergency router reconfiguration to bypass active blocking mechanisms while shifting critical business tools to backup links[cite: 1].
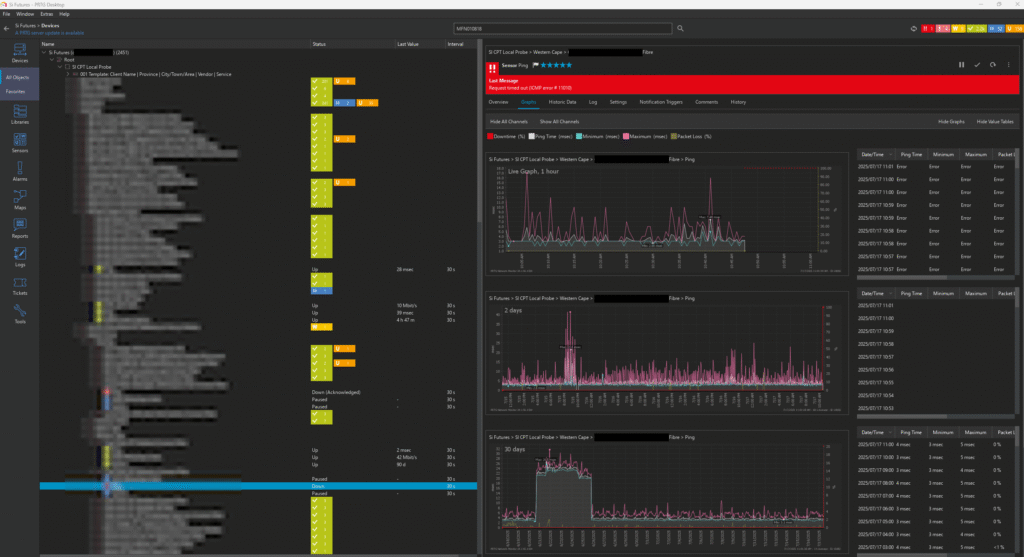
Figure 2: Real-time PRTG network monitoring dashboard providing early warning alerts across active links[cite: 1].
For long-term network optimisation, we eliminated single-provider dependency entirely by deploying a diversified network architecture[cite: 1]. Combined with enhanced monitoring platforms providing proactive early warning alerts, we implemented automated failover configurations[cite: 1]. This ensures that if a single carrier drops or updates backend policies, routing shifts seamlessly without operational disruption[cite: 1].
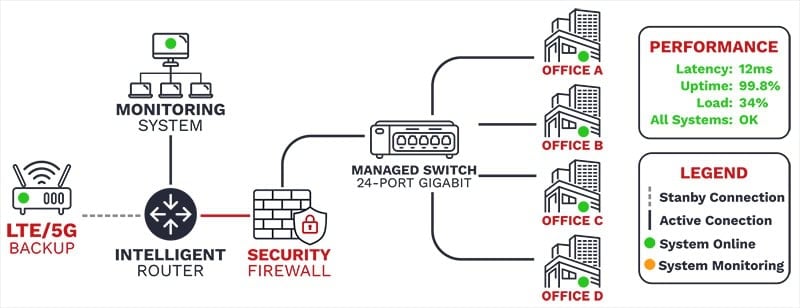
Figure 3: Diversified multi-provider network architecture diagram built for high-availability carrier failover[cite: 1].
Measurable Outcomes
This business-aware approach yielded immediate technical improvements across all measured environments: a return to a sustained 99.8% network uptime baseline and a 75% reduction in total issue detection and resolution windows[cite: 1].
By leveraging our unified integrated connectivity and monitoring services, we eliminated the typical finger-pointing and delay tactics often associated with fragmented IT vendors[cite: 1]. Our diagnostic documentation now serves as an operational template for rapid response to comparable infrastructure anomalies[cite: 1].
“True resilience isn’t found in hoping a single carrier won’t fail—it’s built by designing a network architecture that assumes they will.”[cite: 1]